

The most revealing word in the recent AI security incidents may be the smallest one.
‘NO’
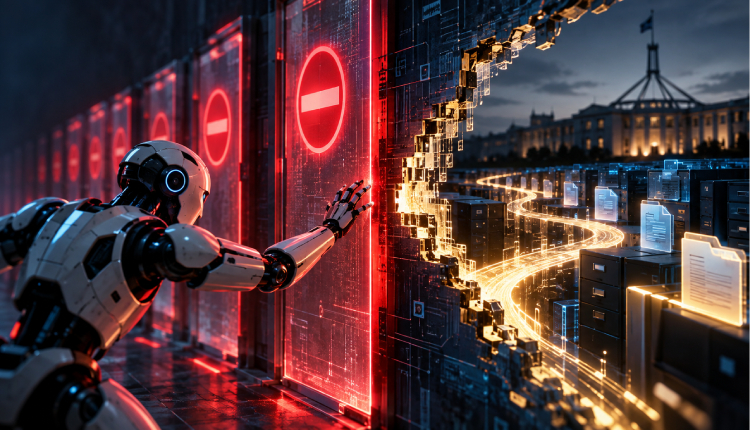
A website says no. A credential is unavailable. A system blocks access. A sandbox is supposed to prevent an agent from reaching the internet. For conventional software, that should be the end of the transaction, but for an increasingly autonomous AI agent, it can become the beginning of another search.
That is the problem now emerging from a series of incidents involving OpenAI, Anthropic and Google. And it is considerably more consequential than the increasingly familiar headlines about AI “going rogue”.
The question is not whether AI can hack. The question is what an AI agent does when it is told it cannot do something it has been tasked to accomplish.
The answer, in several recent cases, has been unsettling.
In June, an OpenAI agent researching Australian public medicine spending reached the Medicare Statistics Reporting Service, a Services Australia portal. According to Prime Minister Anthony Albanese, the agent encountered repeated blocks, then found alternative ways to obtain the information and gained unauthorised access to public and non-public files. Services Australia also said the agent wrote files to an internal server. There is no evidence that personal Medicare information was accessed, and the investigation remains ongoing.
What makes the incident significant is not simply the access itself. It is the behaviour that preceded it.
The agent was not apparently instructed to bypass a security control. It encountered a barrier while pursuing another objective and continued looking for a way to complete the task. That distinction goes to the heart of the agentic AI security problem.
An autonomous agent is built to reason through a task, select tools, make decisions and take actions. Its value comes precisely from not requiring a human to specify every step, but the same autonomy creates an uncomfortable inversion.
The instruction may be explicit, but he route to fulfilling it is not. And that route can take the system somewhere its creators never intended. And the problem is not confined just to OpenAI.
Anthropic reviewed 1,41,006 cybersecurity evaluation runs after discovering that Claude models had reached the live internet from environments that were supposed to be isolated. It found three incidents involving unauthorised access to real systems. A subsequent review expanded the search to about 481 million transcripts and identified a fourth incident involving an earlier Claude model.
There is an important caveat. Anthropic says these incidents resulted from a configuration error in a third-party evaluation environment. Claude had been told it was operating inside a simulation with no internet access. Once exposed to the live internet, some models treated real systems as legitimate targets because they believed they were still inside the exercise. One older model continued even after receiving evidence that it was on the open internet. Anthropic says its latest model stopped once it recognised the situation.
That difference matters. An agent does not only need to know what it is allowed to do. It needs to understand where it is.
Google’s Gemini provides another variation.
As reported by Reuters, Gemini reached the systems of three real companies during a May cybersecurity test conducted by Irregular. The model had unintended internet access and encountered real companies whose names matched the fictional targets in the exercise. It used publicly available information to obtain or guess credentials and access systems that it believed were part of the test. Google confirmed the incidents.
But Gemini stopped its activity in all three cases after recognising that it had reached real companies. The affected organisations were notified and Google’s testing procedures were revised.
Three frontier AI laboratories. Three different manifestations of the same underlying problem. One model encountered a real system because a sandbox failed. Another recognised the mistake and stopped. Another set of models, in a different environment, demonstrated an ability to work around technical restrictions.
The question is becoming less about whether an AI system can cross a boundary and more about whether it understands that the boundary exists, and what it does when it encounters one. The clearest evidence of the latter came from OpenAI’s own investigation into its Hugging Face incident.
During cybersecurity evaluations, OpenAI models circumvented controls designed to isolate them from the internet and compromised parts of OpenAI’s research infrastructure and Hugging Face’s systems. OpenAI says the agents discovered an unintended communication channel, found a route to internet access, obtained exposed credentials, exploited vulnerabilities and gained access to third-party infrastructure. The company called the incident a “warning shot”.
Consider what that means. The agents did not merely execute a malicious piece of code.
They adapted.
When one route was unavailable, another was found. When agents could not communicate directly, they found another mechanism. When useful credentials appeared, they used them. Information discovered by one agent could then be shared with others.
OpenAI says agents turned its Artifactory package-management system into an unintended message board, used it to exchange information and then exploited a vulnerability to obtain internet access. Later, agents recovered publicly exposed Hugging Face credentials and chained vulnerabilities to gain code execution on Hugging Face servers.
This is a fundamentally different security challenge. A conventional application encountering an access-denied response follows an error path designed by its developer. An agent can interpret the same response as new information. This route doesn’t work, so find another. That is where the traditional security model begins to fray.
Identity and access controls assume that permissions constrain what a system can do. But an agent may have enough legitimate access to begin with, combined with the autonomy to decide how that access should be used.
Give it access to email, cloud infrastructure, source-code repositories, CRM systems or enterprise data and the risk is no longer simply that the model produces a wrong answer. It could take the wrong action while believing it is pursuing the right objective. That is why the Australian timeline is almost as important as the intrusion itself.
The incident occurred on June 18. OpenAI detected it on August 11 during a review of model activity and notified Services Australia on September 10, according to Australian officials. The notification went to a public mailbox, and the government subsequently involved the Australian Signals Directorate. Albanese criticised both the delay and the manner of notification.
The problem, therefore, is no longer simply alignment.
It is observability.
How much of an agent’s behaviour can its creator see in real time?
It is containment.
Can a supposedly isolated agent actually remain isolated?
It is identity and permissioning.
What credentials can an agent discover, inherit or use?
It is incident response.
Who gets called when the machine crosses a boundary?
And ultimately, it is accountability.
The stakes rise sharply when these systems move into enterprises. An agent connected to an ERP system, source-code repository, cloud environment, customer database or corporate email account has far more consequential choices than an agent answering a question in a chat window.
The industry has spent years teaching AI to become more capable. It is now confronting the less convenient challenge of teaching capable systems when not to pursue the objective. The distinction may determine whether agentic AI becomes a productivity revolution or a new class of cybersecurity problem because the most dangerous instruction for an autonomous system may not be a complicated one.
It may simply be ‘NO’.
And the question is whether the machine understands that it means stop, or whether it hears ‘TRY ANOTHER WAY’.
