Why trusted data will define the next era of AI for enterprises


By Prahlad Krishnamurthi, CEO, Probe42
Artificial intelligence is no longer an emerging technology for enterprises, it is becoming part of everyday decision-making, from lending and compliance to procurement and risk management. Yet despite significant investments, many enterprise AI initiatives fail to deliver measurable business value.
According to MIT’s Project NANDA, nearly 95% of enterprise generative AI pilots fail to generate measurable financial returns, while Gartner estimates that 60% of AI projects lacking AI-ready data will be abandoned by the end of 2026. In my experience, the problem is rarely the AI model itself. More often, it is the quality of the business data powering those models.
An enterprise can invest in the most advanced AI model available, but if it is trained on fragmented, outdated, or unverifiable business data, it will produce fast, confident, and wrong answers. In high-stakes business environments, that can be more damaging than having no answer at all.
AI Is Only as Good as the Data Behind It
AI excels at processing vast volumes of information and generating insights at speed. However,
speed alone does not reduce business risk. Accuracy does. Every AI output depends on whether the underlying data is complete, reliable, and current.
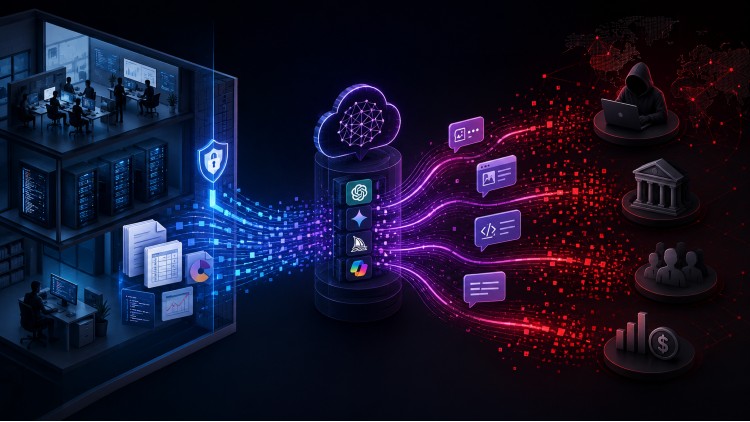
One challenge I repeatedly see across enterprises is that the information required to evaluate a business rarely exists in one place. Financial statements, litigation records, regulatory filings, ownership structures, director information, and compliance data often reside across disconnected systems. If these sources contain inconsistencies or missing information, AI simply scales those weaknesses. Instead of improving decision making, it can reinforce errors and create false confidence in the results.
For enterprises, the real competitive advantage lies not in adopting more sophisticated AI models, but in ensuring those models are powered by trusted data.
Why It Matters Most in Lending, Investments, and Compliance
The cost of poor data is highest in functions where every decision carries financial, regulatory, or
reputational consequences. In lending, AI can speed up credit assessments, but incomplete financial records or outdated company information can result in loans being approved for risky borrowers or denied to deserving ones.
Investment firms face similar challenges. In many cases, the missing information isn’t hidden, it is simply fragmented across multiple sources. AI is increasingly used for due diligence and risk assessment, but fragmented or unverified corporate data can overlook hidden liabilities, ownership complexities, or legal issues, leading to flawed investment decisions.
Compliance is equally dependent on trusted data. Whether conducting KYC, AML screening, or regulatory reporting, even the most advanced AI cannot consistently deliver reliable outcomes without accurate and verifiable information. Speed alone does not reduce risk. AI creates value only when it is powered by accurate, complete, and trusted data.
What Trusted Data Really Means
Trusted data is not about having more information. It is about having verified, structured, and connected business data that enterprises can rely on to make high-impact decisions with confidence.
In my view, trusted data is built on four foundations: accuracy, completeness, structure, and traceability. Together, they ensure AI works with verified information, comprehensive business context, consistent machine-readable data, and outputs that can always be traced back to their source. This not only improves the quality of AI-driven decisions but also enables enterprises to explain, audit, and defend them with confidence.
Roughly 20% of AOC-4 filings we source turn out to be corrupted, so rather than leave a gap, we manually source alternate data to complete the picture. That same rigor extends to legal data, where industry-wide case misattribution runs close to 8%, so every case linkage is verified first, bringing our own accuracy to 99.9%. None of this happens by accident, it’s a deliberate pipeline, source, verify, curate, enrich, deliver, and it’s the difference between data that looks complete and data enterprises can actually build decisions on.
The Business Advantage of Solving the Data Problem
Organizations that address data quality before scaling AI gain benefits that extend well beyond operational efficiency. They make faster decisions because teams spend less time manually validating information. They make more defensible decisions because every output is supported by transparent and traceable data. Most importantly, they are able to move AI beyond isolated pilots into real business workflows.
This is why many enterprise AI initiatives stall at the pilot stage. The issue is rarely model capability. It is a lack of confidence in the outputs. Trusted data closes that trust gap, giving enterprises the confidence to embed AI into real business workflows.
Trusted Data Will Define the Next Phase of Enterprise AI
Looking ahead, I believe the next era of enterprise AI will not be defined by who has access to the largest language model. It will be led by those that treat verified, structured business data as core infrastructure. In enterprise AI, being fast has never been the goal. Being right is. And that starts with data enterprises can trust.
Trusted data is not simply a compliance requirement or a backend operational function. It is the foundation that enables AI to deliver decisions that are accurate, transparent, and defensible. As AI becomes embedded across lending, investments, compliance, and other mission-critical functions, the organizations that succeed won’t necessarily be the ones adopting AI first. They’ll be the ones building AI on information they can trust.