Don’t build an AI data centre. Build a platform that can adapt to AI: Ford’s Gangadhar Yasam on rewiring infrastructure for Intelligent Manufacturing

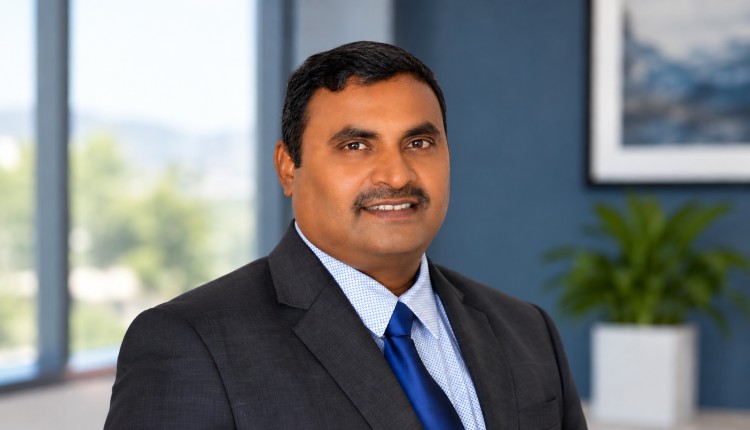

For years, infrastructure has been the line item that boards ask to shrink. Gangadhar Yasam wants it to be the one they ask to grow.
As Lead for IT Infrastructure & Data Center Engineering & Strategy for APAC & MEA at Ford Motor Company, Gangadhar Yasam oversees the digital backbone of a geographically distributed manufacturing footprint. He argues that the backbone is now being redrawn by AI, machine vision, robotics and IoT. Decisions that once could wait for the data centre are being made in milliseconds on the production line. GPU racks are pushing power and cooling assumptions past their design limits. Success, he says, can no longer be measured by servers refreshed or projects delivered.
In this conversation, Yasam makes the case that modernisation should begin with a single question: what business capability can this infrastructure enable? He lays out a maturity path from monitoring to automation, a five-part scorecard for measuring impact, and a blunt warning about the cost of chasing the wrong metrics. His vision of where this leads is of infrastructure that moves “from supporting the business to actively enabling and optimizing it.”
Some edited excerpts from the conversation:
Infrastructure is often viewed primarily as a cost centre. How can technology leaders make the case for infrastructure modernisation as a strategic business enabler, and what measurable business outcomes can it deliver beyond cost savings?
The first shift has to be in how we define infrastructure. It is no longer just servers, networks, data centres and connectivity. In a modern manufacturing enterprise, it is the foundation on which digital manufacturing, automation, analytics, AI and business continuity operate.
The business case should not start with, “How much infrastructure can we save?” It should start with, “What business capability can this infrastructure enable?”
In manufacturing, the value can be demonstrated through measurable outcomes: reduced production downtime, faster deployment of new manufacturing capabilities, improved plant resilience, faster recovery from incidents, better quality of service, and the ability to support new digital workloads without repeatedly redesigning the underlying environment.
When we look at modernisation across a large manufacturing footprint, we must look beyond traditional metrics such as server utilization or infrastructure cost. We should look at how quickly a plant can onboard a new digital capability, how resilient the connectivity is, how quickly incidents can be detected and resolved, and whether the environment can support the next generation of workloads.
My own modernisation journey has reinforced this view. I see infrastructure not as a replacement exercise, but as an enabler for higher-density computing, future AI workloads, improved resilience and more standardized operations across a distributed manufacturing environment.
A good business case connects technology investments directly to business outcomes: availability, speed, resilience, capacity for innovation and operational agility. Cost optimization remains important, but it should be an outcome of better architecture and operations, not the sole reason for modernization.
As AI, robotics, machine vision, IoT and predictive analytics become increasingly important to manufacturing, what changes are required in enterprise infrastructure to support these workloads effectively?
The biggest change is that infrastructure can no longer be designed around a purely centralized model. Manufacturing generates enormous amounts of data at the edge, from machines, sensors, cameras, robots and production systems. Some workloads require decisions in milliseconds, so sending everything to a centralized data centre or public cloud is not always practical.
We need a more distributed architecture spanning edge, plant, regional data centres, private cloud and public cloud, with each workload placed where it makes the most sense.
The requirements change significantly: higher bandwidth, lower latency, deterministic connectivity, stronger segmentation and security, more compute at the edge, and architecture that can handle GPU and accelerator-based workloads.
Machine vision is a good example. A camera-based quality inspection system may generate enormous volumes of data, but the business value often comes from an immediate decision on the production line. The infrastructure must support local processing while allowing relevant data to flow into centralized platforms for analytics, model improvement and enterprise-level insights.
Power and cooling will also become strategic. AI and accelerator-based computing can dramatically increase rack densities, so traditional assumptions around power availability, UPS sizing, cooling and physical space need to be revisited.
The other important change is architectural flexibility. We should not design infrastructure for today’s workload alone. It needs to become AI-ready and workload-aware, so new manufacturing use cases can be introduced without a fundamental redesign every time.
How can organisations use infrastructure management and data centre infrastructure management (DCIM) platforms to move from reactive operations to predictive and data-driven infrastructure management?
The real value of DCIM and infrastructure-management platforms is not in having another dashboard. The objective should be to create a single operational view of the infrastructure and use the data to predict what is likely to happen next.
Traditionally, operations have been reactive: an alarm occurs, someone investigates, and an incident is raised. The next stage is correlation, bringing together information about power, cooling, network, compute, capacity, environmental conditions and asset health. Once that data is available consistently, organizations can begin identifying patterns.
For example, if power consumption, temperature, UPS loading, cooling performance and equipment utilization are monitored together, the organization can identify capacity constraints before they become incidents. Historical trends can also show where infrastructure is approaching its practical limits.
The maturity journey I see is: Monitor → Correlate → Analyze → Predict → Automate.
There is an organisational dimension too. Technology teams need to move from managing individual components to managing service health and business impact. The objective is not to know that a temperature sensor has crossed a threshold. It is to know that a particular plant, production service or critical business capability is approaching an infrastructure risk, and to take corrective action before the business experiences an outage. That is where infrastructure data becomes genuinely strategic.
Remote monitoring, remote commissioning and automation are changing the way infrastructure projects are designed and deployed. What are the biggest opportunities and challenges in adopting these approaches at scale?
Remote operations can fundamentally change the economics and speed of infrastructure deployment, particularly for organisations with large, geographically distributed manufacturing footprints.
The opportunity is significant. Teams can standardise designs, monitor implementation remotely, perform many validation activities without being physically present, and reduce dependence on large deployment teams travelling between locations. That improves deployment speed, consistency and operational visibility.
However, remote commissioning does not mean eliminating physical validation. That is an important distinction.
The challenge is creating sufficient standardisation around design, documentation, acceptance criteria, instrumentation, testing and escalation. If every site has a different architecture, or a different interpretation of what “ready for operations” means, remote commissioning becomes difficult.
The answer is to design for remote operability from day one: standardized architectures, digital documentation, clearly defined commissioning checklists, remote telemetry, automated testing wherever practical, secure remote access and strong local escalation processes.
There is also a people and skills dimension. Remote operations need engineers who can interpret data and diagnose problems remotely, rather than simply respond physically to an alarm.
The objective should not be “remote instead of physical.” It should be digital-first operations, with physical intervention reserved for activities that genuinely require it.
As AI workloads drive demand for high-density compute, GPUs, power and advanced cooling, how should manufacturers rethink their data center strategies to accommodate these requirements while maintaining efficiency and sustainability?
AI is forcing organisations to rethink data centres from the rack level all the way to the facility level.
Historically, many enterprise data centres were designed around relatively predictable compute densities. AI changes that. GPU-based workloads can create much higher power and thermal densities, so simply adding more racks to an existing facility may not be a sustainable strategy.
Manufacturers should start with workload and power planning, rather than space planning. Before adding AI capacity, they need to understand where workloads will run, what latency they require, what compute density they demand, and whether they belong at the plant, edge, private data centre or public cloud.
Power infrastructure becomes particularly important. UPS capacity, power distribution, rack-level availability, redundancy and the ability to provision additional capacity need to be assessed together.
Cooling also has to evolve. Depending on density, traditional air cooling may not be enough, and organisations need to evaluate liquid cooling or other advanced thermal-management approaches. These questions need to be addressed well ahead of deployment, rather than waiting for AI workloads to arrive and then discovering the facility cannot support them.
Sustainability must be built into the architecture. Efficiency is not simply about reducing energy consumption; it is about getting more useful computing output from every unit of power, cooling capacity and physical infrastructure.
So I would summarise the approach as: Don’t build an AI data centre. Build a data-centre platform that can adapt to AI. That distinction matters because the technology and workload landscape will continue to change.
How should organisations measure the success of an infrastructure modernisation program? Which KPIs best demonstrate its impact on manufacturing performance, business agility, resilience and innovation?
I would avoid measuring modernisation by the number of servers replaced, infrastructure refreshed or projects completed. Those are delivery metrics, not business outcomes. I would measure it across five dimensions:
#1 Manufacturing performance: How has modernisation affected production availability, unplanned downtime, latency for critical manufacturing systems and the ability to support plant operations?
#2 Resilience: How quickly can we detect, isolate and recover from infrastructure failures? How resilient are critical connectivity, power and computing environments? How much dependency exists on individual components or locations?
#3 Business agility: How quickly can a new plant capability, application, sensor network, analytics platform or digital manufacturing solution be deployed?
#4 Operational efficiency: Energy efficiency, capacity utilization, automation levels, incident volumes, mean time to detect and resolve, and infrastructure management effort.
#5 Innovation capacity: Can the infrastructure support AI, machine vision, robotics and advanced analytics without major redesign?
I also believe one of the most important KPIs is time-to-enable. If a business wants to introduce a new digital manufacturing capability, how long does it take to make the underlying infrastructure available? If modernization reduces that from months to weeks, or weeks to days, that is a strategic business outcome.
Ultimately, the scorecard should connect infrastructure metrics to business metrics. If the infrastructure team is celebrating higher utilization while the plant is experiencing more downtime, we are measuring the wrong thing.
Looking ahead three to five years, how do you expect enterprise infrastructure to evolve as AI, automation and intelligent manufacturing become more deeply integrated?
Over the next three to five years, I expect enterprise infrastructure to become much more distributed, intelligent, automated and workload-aware. The traditional boundaries between data centre, cloud, network, edge, security and plant infrastructure will increasingly blur.
More computing will move to the edge where latency, operational continuity or data volume require it, while centralised environments will continue to provide large-scale computing, data platforms and enterprise services.
AI will also become part of infrastructure operations itself. Teams will use it not only to support business applications but also to predict failures, optimize capacity, identify anomalies, improve energy efficiency and automate operational decisions.
Another major change will be the convergence of infrastructure disciplines. Network, compute, storage, cybersecurity, power, cooling and facilities can no longer be planned independently when workloads become dynamic and compute-intensive.
For manufacturing, I expect the physical and digital worlds to become even more tightly integrated. A production line will increasingly behave like an intelligent computing environment, with sensors, robotics, machine vision, edge computing and analytics working together.
Infrastructure leadership will evolve too. The leader of the future cannot think only in terms of technology assets. They need to understand manufacturing operations, business continuity, energy, cybersecurity, data, AI workloads and economics as one interconnected system.
My expectation is that infrastructure will become adaptive rather than static, able to sense demand, understand workload requirements, dynamically allocate resources and increasingly automate its own operations.
The real transformation will not be simply from on-premises to cloud, or from traditional infrastructure to AI infrastructure. It will be the transition from infrastructure that supports the business to infrastructure that actively enables and optimizes the business.