When the suite goes dark: What Microsoft 365’s November outage means for CIO resilience plans

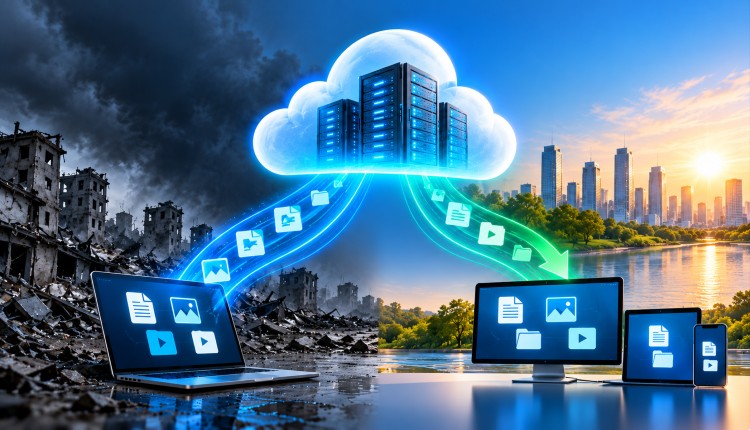

When a major cloud platform fails at scale, who decides which customers get restored first? It is a question most CIOs have never put to their providers. After the November 12 Microsoft 365 disruption, it is one they can no longer avoid.
The incident hit Exchange Online mailbox access and spread to other Microsoft services. Microsoft’s preliminary post-incident assessment traced it to a latent defect tied to an earlier infrastructure fix, which surfaced under increased load and reduced capacity. Services came back progressively, with the last affected customers and regions restored by November 14.
For enterprises that run daily operations on Microsoft 365, the lesson goes beyond one bad week. Cloud availability is not just an infrastructure concern. It is a business continuity issue.
One suite, one point of failure
Microsoft 365 is no longer an office productivity suite. For many organisations it is the digital workplace itself, linking email, collaboration, document management, identity-linked workflows, endpoint management and security operations. Employees get a familiar environment, IT simplifies administration, and security and collaboration policies can be standardised.
That convenience carries concentration risk. When many functions share one ecosystem, a single disruption spreads. An email outage becomes a collaboration problem. A fault in identity dependencies blocks application access. Security and endpoint management workflows stall.
The blind spot is that enterprises tend to assess the resilience of individual applications while overlooking the dependencies they share. In Greyhound Research’s analysis, Microsoft 365 Outage: When the Suite Goes Dark, Restoration Order Becomes the Control, Greyhound Research argues that the real concern is not whether one service is up, but how much of the enterprise depends on it staying up.
 Sanchit Vir Gogia, Chief Analyst at Greyhound Research, puts it bluntly: “On 12 November, Microsoft 365 did not fail as a set of products. It failed as one system, and the mail and meetings that carry approvals between a company’s other systems stopped together. Enterprises have priced Microsoft 365 as a licence, never as a single point of failure. By Microsoft’s own account, six of the ten major multi-service outages since January 2023 began with a change Microsoft itself made. Consolidation remains the right strategy for most enterprises, but it needs a rehearsed plan for the day the suite goes dark. When everything fails at once, the order in which services come back becomes the control.”
The takeaway for CIOs is not to unwind consolidation. It is to find where dependencies sit and to ensure critical processes can keep running when a common platform goes down.
Restoration order: the question buyers forget to ask
Restoring a large cloud provider’s services across regions, infrastructure environments and customer workloads is complex. Recovery depends on available capacity, technical dependencies, regional infrastructure and how restoration work is sequenced. So where does your organisation stand in that queue, and do you have any assurance about it?
Greyhound Research points to the reported case of the Australian government, whose agreement with Microsoft was reportedly activated to secure priority during recovery. The analysis notes the arrangement was non-binding, but argues the issue deserves far more attention from enterprise buyers.
The stakes are highest in banking, healthcare, government, manufacturing and utilities. A bank must keep transaction and customer-service operations running. A hospital needs uninterrupted access to administrative and clinical workflows. A manufacturer relies on digital systems for production coordination and supply chain visibility. The impact of an outage is not uniform, and CIOs should not assume their business criticality earns preferential treatment in a recovery. They should press providers on restoration sequencing, escalation arrangements and the contractual commitments available for critical workloads.
Why SLAs fall short
Cloud service-level agreements centre on availability percentages and financial remedies. But a service credit cannot make up for delayed customer transactions, missed commitments, disrupted production or lost employee productivity.
There is also a gap between contractual availability and operational resilience. A platform can meet its monthly uptime commitment and still fail during a critical business period. CIOs need to look past headline uptime figures and make sure contracts cover incident notification, escalation procedures, access to root-cause analysis, recovery commitments and the process for claiming credits. Where possible, they should explore negotiating additional recovery commitments for business-critical services. The aim is transparency and accountability, not reliance on compensation after the damage is done.
A security problem too
The outage also lands on the CISO’s desk. Email protection, endpoint management, identity controls, information governance and threat detection increasingly depend on interconnected productivity services. When one fails, security teams must know exactly which capabilities still work and which are degraded.
Can administrators reach critical security information through another channel? Can incident responders coordinate if their primary collaboration platform is down? Do endpoint policies and protections keep operating independently? CIOs, CISOs and infrastructure teams should answer these together: map security dependencies, document alternative operating procedures and test incident response without the primary productivity environment. Emergency access must be designed carefully, so continuity measures do not weaken controls or open new vulnerabilities in an already difficult moment.
Seven priorities for CIOs
1. Identify the processes that cannot stop. Work with business leaders to pinpoint operations that must continue through a cloud outage, such as customer support, financial approvals, regulatory reporting, manufacturing coordination and emergency communication. Document an alternative operating procedure for each.
2. Map technology dependencies. An application inventory is not enough. Understand how applications rely on identity services, APIs, collaboration platforms, email and external cloud infrastructure, so you can see common points of failure and which functions a single disruption would hit.
3. Set up independent communication channels. Crisis communication should not depend on the platform that may be down. Maintain alternative channels for executive communication, incident coordination and critical business teams.
4. Test continuity scenarios. Disaster recovery drills tend to focus on infrastructure. Extend them to simulate the loss of an entire productivity ecosystem, and find out whether employees can still perform essential tasks without their usual collaboration and communication tools.
5. Revisit cloud contracts. Review incident notification commitments, escalation procedures, restoration transparency, root-cause disclosures and service-credit provisions. For critical workloads, explore whether enhanced recovery arrangements are commercially and technically feasible.
6. Keep essential information reachable. Identify the minimum information needed to sustain operations, including emergency contacts, critical operational records, approval procedures and key documentation, and make it available through secured, independent mechanisms.
7. Make cloud concentration a board-level risk. Include it in enterprise risk assessments and continuity reviews. Boards need visibility into critical provider dependencies, the likely impact of prolonged disruption and the measures available to keep essential operations going.
Resilience is the enterprise’s job
The outage is not an argument against the cloud. The operational and economic benefits of integrated platforms remain substantial. But it sharpens the difference between cloud availability and enterprise resilience. Providers are responsible for operating their infrastructure and restoring service. The responsibility for keeping the business running stays with the enterprise.
The next phase of cloud strategy has to go beyond platform selection, cost optimisation and application modernisation. It must address dependency management, recovery assurance and operational independence.
The real measure of cloud resilience is not how well an enterprise operates when its cloud services are available. It is how effectively it continues to function when they are not.