AI models to AI agents: What it takes to scale intelligent systems


By Ramakant Yadav, Co-Founder, Scalar Field
Enterprise AI has quietly changed shape over the past eighteen months. The question is no longer whether a model can produce a useful answer. It is whether a system built around that model can be trusted to act on one. That shift, from generating output to taking action, is where most of the engineering difficulty now sits.
Capital markets illustrate the gap more sharply than most sectors. Trading terminals have historically been passive dashboards, dense with data but entirely dependent on a human to form the hypothesis, pull the inputs, test the idea and place the order. The software displays. The analyst works. Agentic systems invert that relationship, and inverting it turns out to be far harder than improving the model underneath.
Why Is Scaling Agentic AI So Much Harder Than Scaling Models?
The adoption data captures the awkwardness. McKinsey’s 2026 global survey found 40% of large enterprises scaling AI agents in at least one function, up from 27% a year earlier, while the share attributing any EBIT contribution to AI stayed flat at 37%. Deployment is accelerating. Financial impact is not keeping pace.
Agents also fail differently from conventional software. A traditional system throws an error that can be caught and handled. An agent makes a plausible but wrong decision early in a sequence, executes the remaining steps competently, and delivers something confidently incorrect.
Reliability compounds unforgivingly. If each step in a chain is 95% reliable, a twenty-step task succeeds around a third of the time. No individual component appears broken. The system still does not work. Pilots rarely surface this, because a demonstration runs once under supervision, while production runs continuously without it.
Building AI Agents That Can Move Beyond Insights to Action
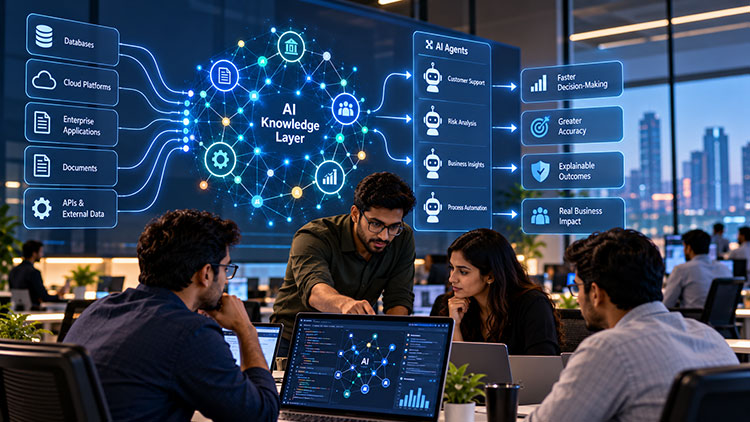
The architectural response gaining ground is to stop asking a single system to do everything. Language models are strong at interpretation, planning and deciding what matters. They are considerably weaker at arithmetic, state management and precise execution.
Systems built for high-stakes environments increasingly separate these responsibilities, placing an agent reasoning layer above a deterministic, event-driven execution layer. The model interprets the question and decides what should be tested or acted upon. Deterministic code performs the calculation and carries out the action.
In markets, that distinction is unforgiving. An agent might read an earnings surprise, check it against insider transaction filings, test the pattern across a decade of prices and macro series, and only then route an order. Reasoning belongs in the first four steps. The fifth needs predictable latency and exact arithmetic, neither of which a language model reliably provides.
What Does the Infrastructure Actually Have to Carry?
Cost has emerged faster than most teams anticipated. The same McKinsey survey found roughly one in five organisations reporting that AI operating costs, including tokens, are already limiting usage. An agent caught in a loop is not merely wrong; it is expensive, and unbounded consumption is a common and under-reported reason pilots get cancelled.
Integration consumes more engineering time than the model work does, and this is where the real-time requirement bites. A research agent in markets has to reconcile regulatory filings, live news wires, options data, macroeconomic releases and brokerage execution records, each with different latency, formats and failure modes. Enterprises in other sectors face the same problem of wearing different clothes.
Two further requirements decide whether a system survives production. Persistent memory comes first, since an agent that forgets yesterday’s conclusion remains a demonstration rather than a dependency. Isolation follows, with each agent operating inside its own boundary and its own allocated resources. In portfolio contexts that extend to capital itself, with cash ringfenced and performance tracked separately per strategy, a weak one fails in its own lane.
Can Anyone Explain How the System Reached Its Decision?
Observability is where many deployments go wrong. Teams instrument outputs, but by the time a bad output appears, the error occurred several steps earlier. Without visibility into what an agent considered and why it chose one path over another, incident reviews become mere guesswork.
This is becoming commercially decisive rather than merely technical. Once agents act instead of advise, users want to interrogate conclusions. Reasoning trails, audit logs and backtests that reproduce exactly are shifting from compliance overhead to genuine differentiation.
Balancing AI Autonomy with Human Oversight
The useful question is not whether an agent can act, but how much damage a wrong action causes. Blast radius is the real control: isolated resources, hard limits, rate caps, and a human approval gate for anything outside a defined mandate.
Indian regulators have moved in the same direction. SEBI’s algorithmic trading framework describes the kill switch as an emergency function and the last level of defence against an algorithm malfunctioning, and the regulator has signalled that its forthcoming AI guidelines will mandate human oversight alongside similar controls.
The accountability point is the one that organisations most often miss. Most enterprises buy their AI rather than build it. Procurement does not transfer liability.