
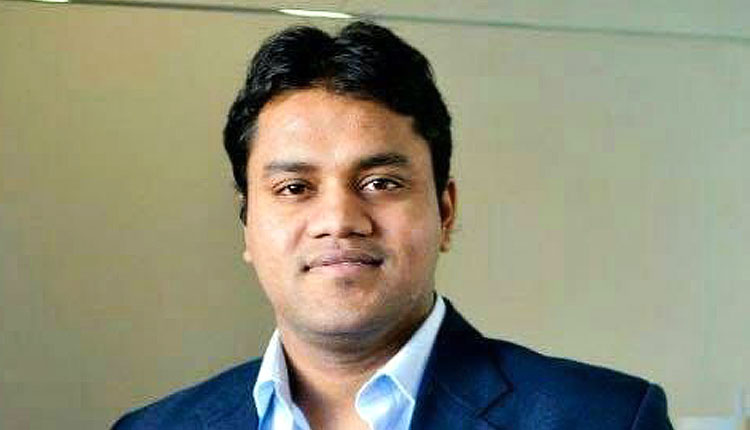

By Anuj Gupta, Founder & CEO, KiteFishAI
For much of the generative AI era, progress has been closely associated with scale. Bigger models, more parameters, larger training datasets, and increasingly expensive compute became the dominant measures of technological advancement.
That approach has delivered remarkable results. General-purpose foundation models can write code, analyse documents, generate images, reason across complex questions, and perform tasks that would have seemed impossible only a few years ago.
But the next phase of AI may not be defined by making these models simply bigger.
It may be defined by making them more specialised.
The question enterprises are increasingly asking is no longer, ”How large is the model?” It is: How well does it understand my business?”
General intelligence has an enterprise limitation
A general purpose model is trained to perform across a very broad range of tasks. That breadth is its greatest strength, but also creates limitations when it is deployed in specialised environments.
Consider a large bank processing loan applications. The task is not simply to understand a document. An AI system may need to extract information from income statements, tax documents and bank records, understand financial terminology, apply internal lending policies, identify missing information and flag exceptions for human review.
A general-purpose model may be capable of performing each of these tasks individually. But an enterprise deployment also needs consistency, traceability, predictable latency, data controls and alignment with the institution’s specific processes.
This creates an important distinction between general intelligence and useful intelligence.
The most capable model in a benchmark is not automatically the most useful model in a production environment.
The economics are changing too
There is also a practical reason for this shift.
Running increasingly large models for every enterprise task can be expensive and inefficient. Many workloads do not require the full capabilities of a frontier model.
Take the banking example further. If millions of routine documents need to be classified, fields extracted and applications routed every month, sending every request to the largest available model may be unnecessary. A smaller domain-optimised model could handle the predictable, high-volume work, while a more capable model could be brought in when an application contains unusual circumstances or requires deeper reasoning.
The architecture becomes less about choosing the model and more about choosing the appropriate model for each task.
That distinction could have significant implications for enterprise AI economics. Cost, latency and compute requirements become part of the intelligence strategy rather than merely infrastructure considerations.
Specialisation is more than fine-tuning
The idea of specialised intelligence is sometimes reduced to fine-tuning an existing foundation model on company data. That is only one part of the picture.
Specialisation can happen at several layers.
Models can be trained on domain-specific data. They can be optimised for particular reasoning patterns. They can be designed for specific latency or compute constraints. They can be combined with retrieval systems, domain tools and enterprise knowledge bases.
The surrounding system can also determine how intelligence is applied.
This is particularly important as enterprises move towards agentic systems. An agent operating in a financial workflow may need access to a different set of tools, policies and validation mechanisms than an agent operating in software development.
The intelligence therefore does not live entirely inside the model.
It increasingly lives across the model, the data, the tools, the context and the orchestration layer.
Smaller does not automatically mean better
The shift towards specialised intelligence should not be interpreted as the end of large foundation models.
Large models will continue to play an important role. They are particularly valuable for broad reasoning, complex tasks and situations where the required context is difficult to anticipate.
The more likely future is heterogeneous.
Enterprises may operate a portfolio of models rather than relying on a single model for everything. A smaller specialised model may handle the majority of routine workloads, while larger models are called when greater reasoning capability is required.
This approach also introduces an important engineering challenge: deciding which model should handle which task.
Model routing, evaluation and continuous monitoring could therefore become as important as model training itself.
From model-centric AI to system-centric AI
The broader change is a move away from thinking of AI as a single model.
The winning enterprise architecture may not be the one with the largest model. It may be the one that can reliably determine what intelligence is required for a particular problem and deploy it efficiently.
That means evaluating models on more than generic benchmarks.
Enterprises will increasingly need to measure accuracy on their own workflows, reliability, latency, cost, security, explainability, and the ability to operate within their infrastructure and regulatory constraints.
This also changes the role of AI teams. Instead of continually asking how to adopt the newest model, they will need to ask which combination of models, data and systems produces the best outcome for a particular business process.
The AI race is therefore entering a more nuanced phase.
The first chapter was about building models that could do more.
The next chapter may be about building intelligence that knows exactly what it needs to do.
In that world, bigger will remain an advantage in some situations. But it will no longer be the only definition of progress.
The real competitive advantage may come from knowing where general intelligence ends and specialised intelligence begins.